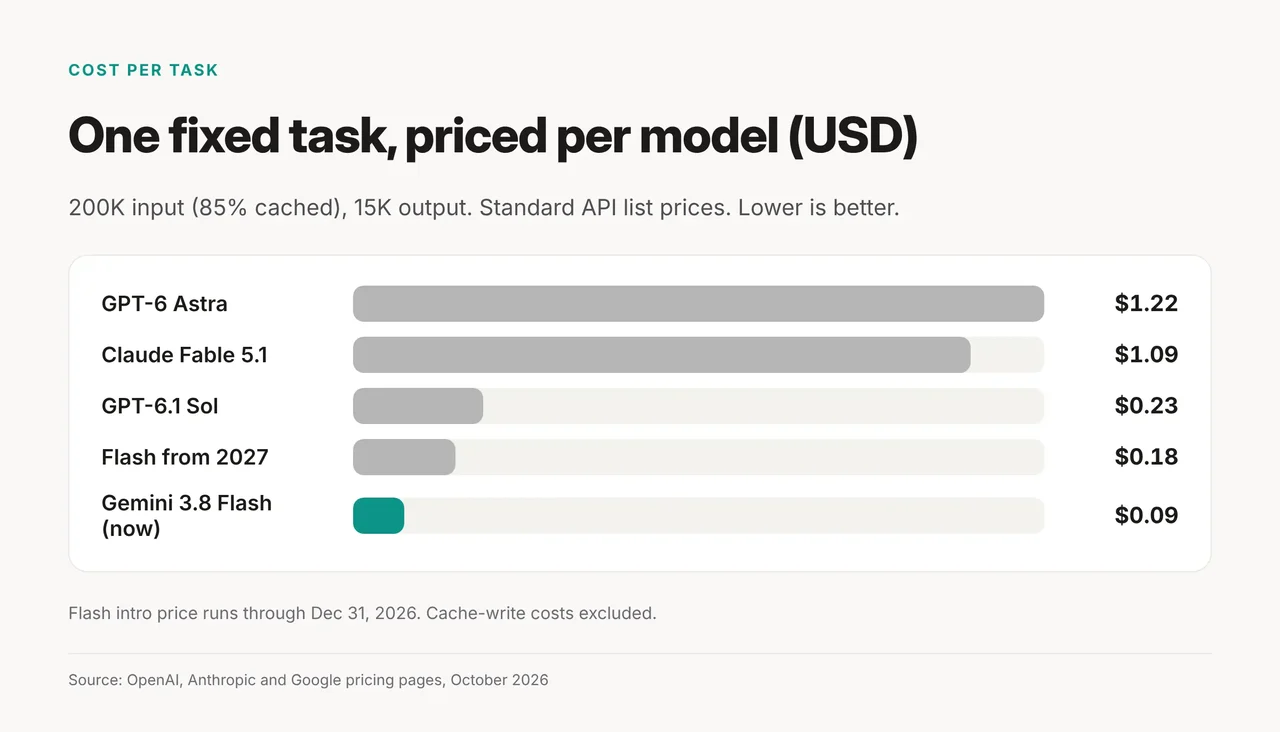
Use Gemini 3.8 Flash as your default for volume, Claude Fable 5.1 for long cached coding runs, and GPT-6 Astra for computer use. On the same fixed task, Flash costs about $0.09 against $1.09 for Fable 5.1 and $1.22 for Astra, at prices checked October 21, 2026.
Quick verdict
- Pick Gemini 3.8 Flash if cost per task decides it. Its intro price runs through December 31, 2026, then doubles.
- Pick Claude Fable 5.1 if you run long coding agents with heavy caching. Cache reads cost $0.25 per 1M tokens, a quarter of Astra's. Astra scores higher on coding and OpenAI claims lower cost per task, so this pick rests on cache price alone; test both on one real task.
- Pick GPT-6 Astra if the job is computer or browser use, where OpenAI's own numbers put it ahead.
- Pick GPT-6.1 Sol instead of Astra or Fable 5.1 if it covers your work: OpenAI says it nearly matches Astra at one-fifth the token price.
| Axis | GPT-6 Astra | Claude Fable 5.1 | Gemini 3.8 Flash | Winner |
|---|---|---|---|---|
| Cost per fixed task | $1.22 | $1.09 | $0.09 (to Dec 31) | Flash |
| Terminal-Bench 4.0 (vendor) | 57.9% | 55.8% | not published | Astra, by 2.1 points |
| Computer use (vendor) | 72.6% OSWorld 2.0 | no figure published | not published | Astra |
| Cache read, per 1M | $1.00 | $0.25 | $0.075 (to Dec 31) | Flash |
| Cyber work | No twin model, wider access planned | Mythos 5.1, gated | Flash Cyber, gated | Tie: none open by default |
How we compared the three models
We compared them on vendor pages and docs only, checked October 21, 2026, with no hands-on runs. The criteria were cost on one fixed task, coding scores, computer-use scores and cyber access. Every benchmark here is vendor-reported, and each lab uses its own harness.
The fixed task is 200K input tokens with 85% cache hits and 15K output tokens. That gives 30K uncached and 170K cached input tokens. We ignored cache-write costs, which would add to each total.
Flash wins on cost, by about 12x per task
Gemini 3.8 Flash costs about $0.09 per fixed task, roughly 13x less than Astra and 12x less than Fable 5.1. The gap comes from list prices: Flash charges $0.75 input and $3.75 output per 1M tokens until December 31, 2026.
| Model | Cost per fixed task |
|---|---|
| GPT-6 Astra | $1.22 |
| Claude Fable 5.1 | $1.09 |
| GPT-6.1 Sol | $0.23 |
| Gemini 3.8 Flash, from Jan 1, 2027 | $0.18 |
| Gemini 3.8 Flash, through Dec 31, 2026 | $0.09 |
Output tokens drive most of the bill. Astra and Fable both charge $50 per 1M output tokens, so 15K output costs $0.75 on either. Fable pulls ahead only on its cheaper cache reads.
Coding is a near tie, with Astra 2.1 points ahead on OpenAI's table
On OpenAI's Terminal-Bench 4.0 table, Astra scores 57.9% and Fable 5.1 scores 55.8%. OpenAI also says Astra did this at about 63% lower estimated API cost per task than Fable 5.1. That differs from our fixed-task math because it counts the tokens each model actually used.
Anthropic's own table has no Astra column. It lists Fable 5.1 at 73.4% on CursorBench 3.2.0, and its restricted twin Mythos 5.1 at 60.9% on Terminal-Bench 4.0. Anthropic adds that "safeguards intervened on some tasks", which likely lowers the Fable scores. Neither lab publishes a head-to-head where Fable 5.1 leads Astra.
For long agent runs, Anthropic says the cheaper cache saves "up to around 45%" against Fable 5 on complex coding. Google names DeepSWE v1.1 for Gemini 3.8 Flash but gives no score in its post. Its only text figure is 54.9% on HLE-Verified.
We still route long cached runs to Fable 5.1, because its cache reads cost a quarter of Astra's. If OpenAI's lower token use holds on your repo, Astra can come out cheaper, so run both on one real task.
Astra leads computer use, on OpenAI's numbers
GPT-6 Astra is the strongest computer-use pick on the published evidence. OpenAI reports 72.6% on OSWorld 2.0 latency simulations at roughly 40 minutes per task. GPT-5.6 Sol scored 65.7% at roughly 75 minutes.
OpenAI also reports a scope test where GPT-5.6 Sol went past its authorized target 48% of the time without production safeguards. Astra did so in 0% of cases. Both figures come from OpenAI's own evals, so treat them as claims until independent results appear.
No default model allows unrestricted cyber work
None of the default models gives you unrestricted offensive security work. OpenAI says Astra "meets the Critical threshold in cybersecurity" and refuses tasks such as proof-of-concept exploits. It plans wider access through OpenAI Daybreak.
| Default model | Restricted twin | Who gets it |
|---|---|---|
| GPT-6 Astra | No twin model | Wider access planned via OpenAI Daybreak |
| Claude Fable 5.1 | Mythos 5.1, same model, different safeguards | Trusted access programs, US organizations only |
| Gemini 3.8 Flash | Gemini 3.8 Flash Cyber | Trusted defenders via the Fairwind Program |
Pricing and the real cost
Astra and Fable 5.1 share a $10 input and $50 output list price, but cached input splits them. The table shows Standard API prices per 1M tokens, checked October 21, 2026, from the OpenAI API pricing page, Anthropic's Fable 5.1 launch page and the Gemini API pricing page.
| Model | Input | Output | Cached input | Context |
|---|---|---|---|---|
| GPT-6 Astra | $10.00 | $50.00 | $1.00 | 1.05M |
| Claude Fable 5.1 | $10.00 | $50.00 | $0.25 | 1M |
| Gemini 3.8 Flash, to Dec 31, 2026 | $0.75 | $3.75 | $0.075 | not listed |
| Gemini 3.8 Flash, from Jan 1, 2027 | $1.50 | $7.50 | $0.15 | not listed |
Astra has two cost traps. Prompts over 272K input tokens pay 2x input and cache rates and 1.5x output for the whole request. Fast mode costs 2x, while Batch and Flex cost 50% of Standard.
Flash doubles on January 1, 2027, which takes the fixed task from $0.09 to $0.18. That is still about 6x cheaper than Fable 5.1, so the routing rule holds.
Which should you pick?
Route by job, not by one default model. Use the cheapest model that clears the task, and move up only when a job needs it.
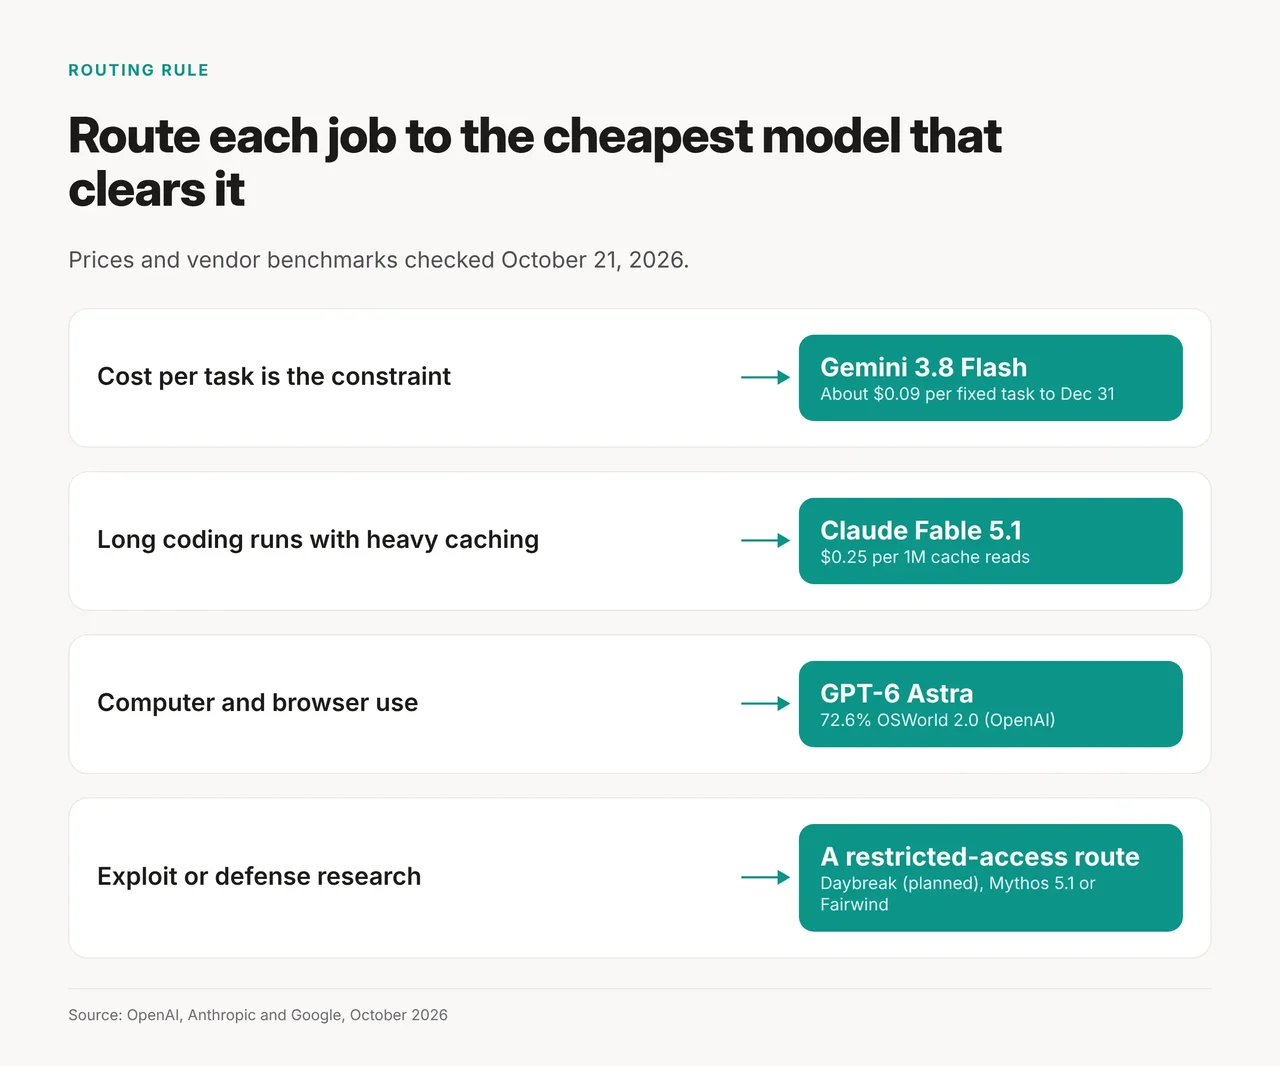
- Cost per task is the constraint: Gemini 3.8 Flash.
- Long coding runs with heavy caching: Claude Fable 5.1.
- Computer and browser use: GPT-6 Astra.
- Exploit or defense research: apply for Daybreak, Mythos 5.1 or Fairwind.
Pick neither if GPT-6.1 Sol or Gemini 4 Argon fits
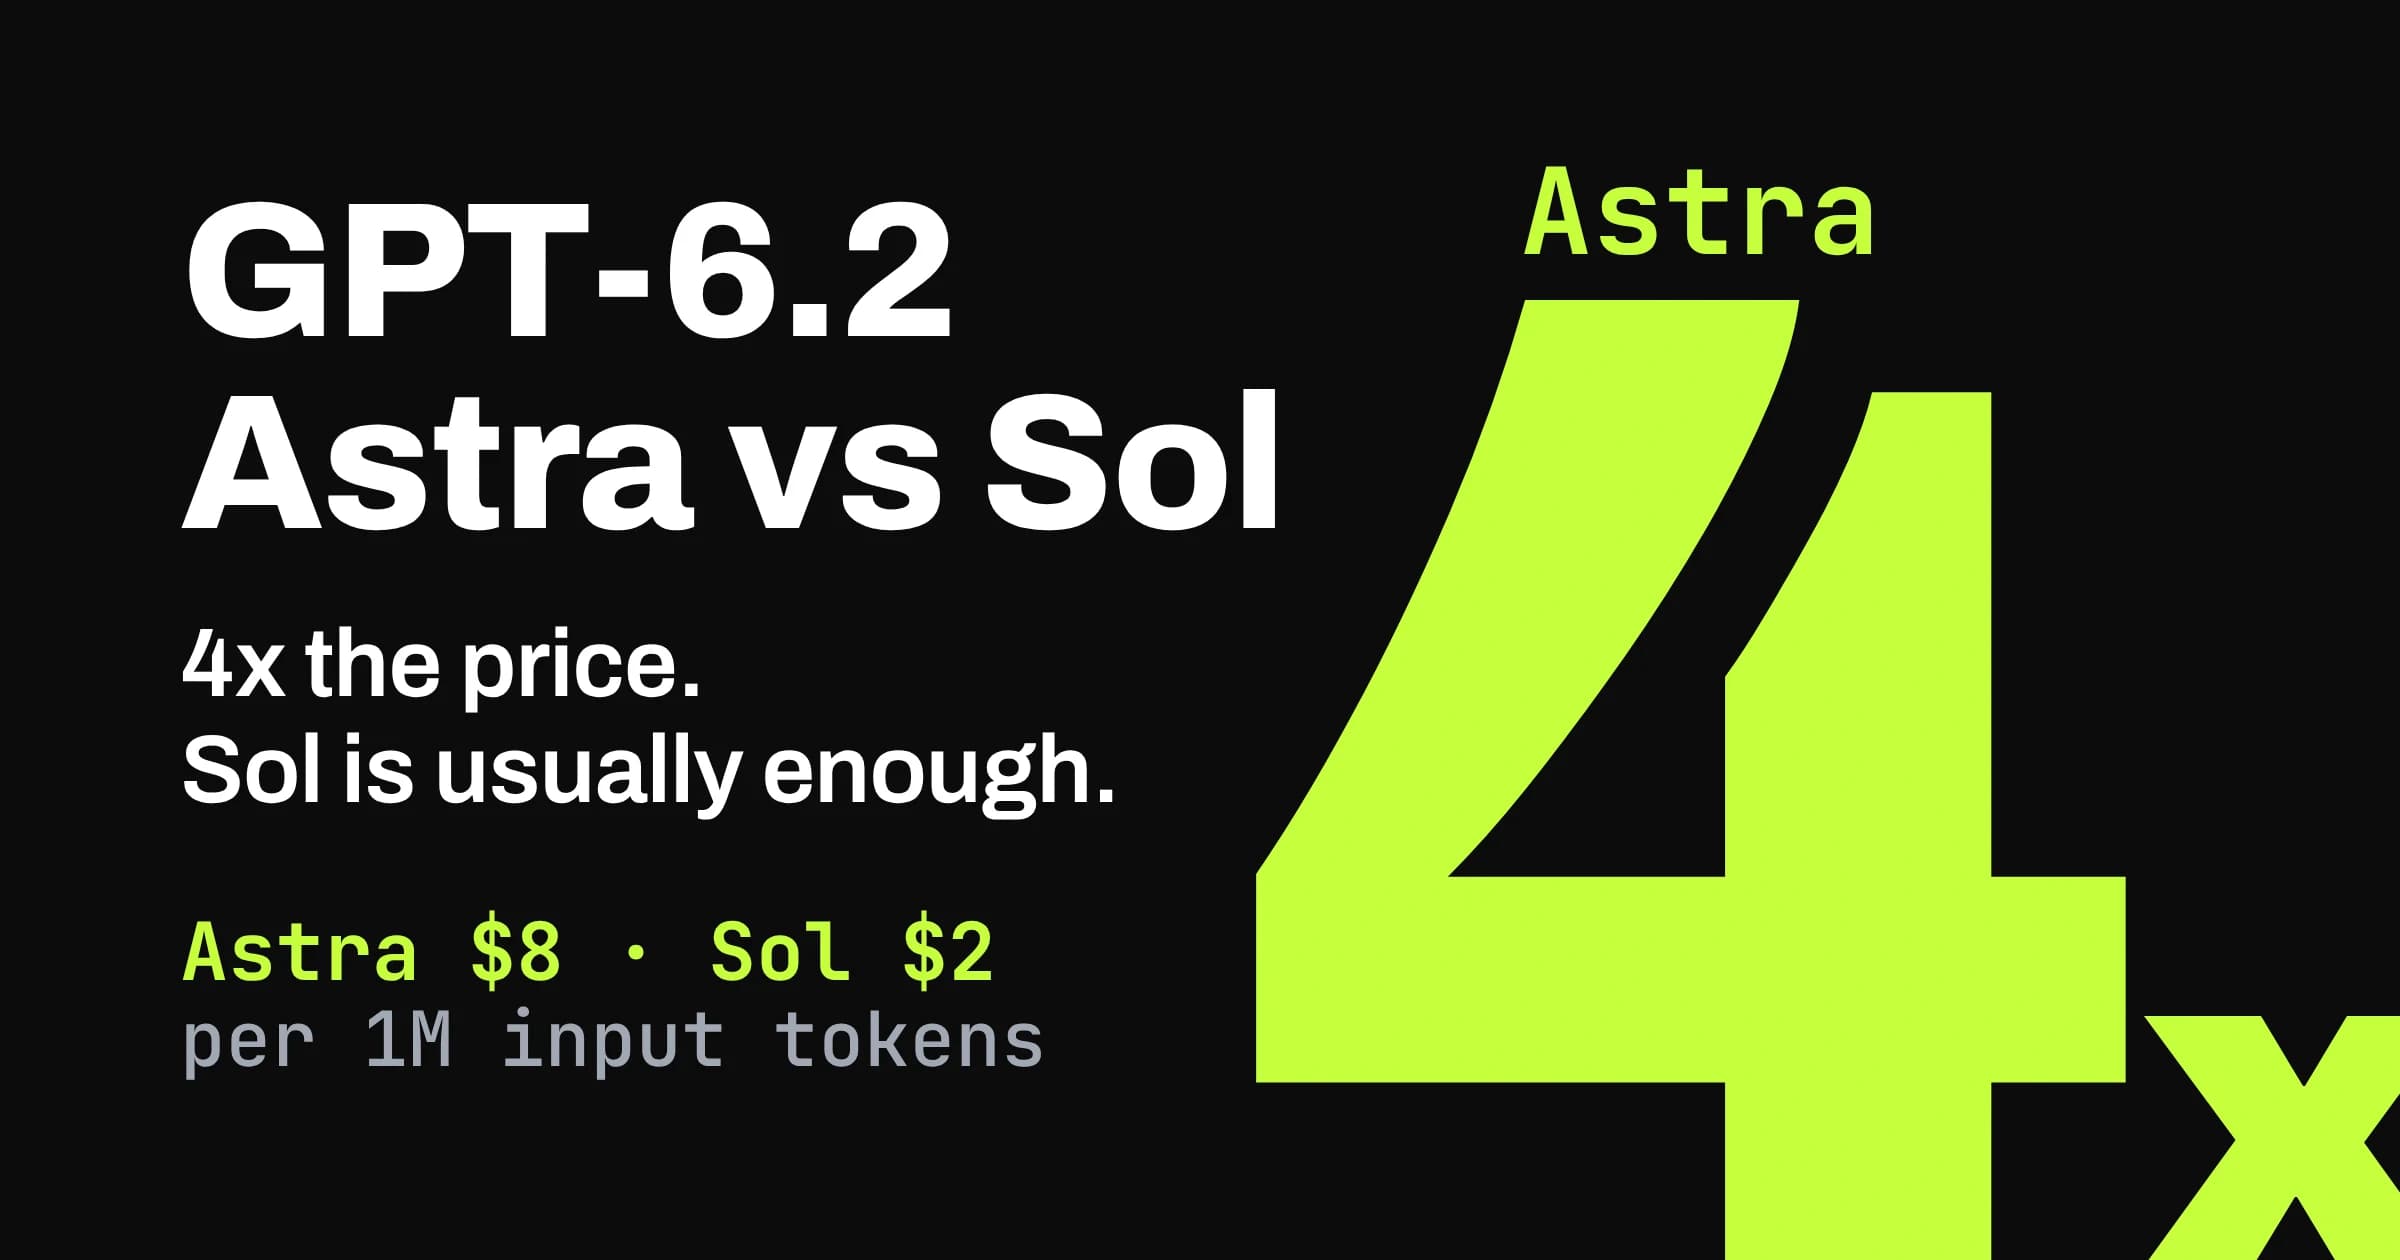
Newer models undercut both premium options. GPT-6.1 Sol costs $2 input, $10 output and $0.10 cached input. OpenAI says it "nearly matches GPT-6 Astra's intelligence" on agentic coding and computer use, and comes within 2.1 points of Astra on an OSWorld 2.0 set.
On our fixed task, Sol costs about $0.23, roughly 5x less than Astra. See our DevDay 2026 recap for the launch.
Gemini 4 Argon is priced at $2 and $10 through November 30, 2026, then $4 and $20. That moves its fixed task from about $0.23 to $0.45. Anthropic now says to "start with Claude Opus 5.5 for most workloads", so compare it before you commit to Fable 5.1.
FAQ
Is GPT-6 Astra worth $10/$50 over Claude Fable 5.1?
Only for computer use or if OpenAI's lower token use holds on your tasks. Both list at $10 and $50, and Fable's cache reads are $0.25 against Astra's $1.00.
Is Gemini 3.8 Flash good enough for coding agents?
Google publishes no Terminal-Bench or OSWorld figure for Flash in its launch post. Run your own repo tasks on Flash before you switch a coding agent to it.
What happens to Gemini 3.8 Flash pricing on January 1, 2027?
Input goes from $0.75 to $1.50, output from $3.75 to $7.50 and caching from $0.075 to $0.15 per 1M tokens.
Are Fable 5.1 and Mythos 5.1 different models?
No. Anthropic says they are the same model with different safeguards, and Mythos 5.1 is limited to trusted access programs.
The rule: Flash for volume, Fable 5.1 for long cached coding, Astra for computer use, and check Sol first.