
On October 17, 2026, DeepSeek upgraded its Flash API model to DeepSeek-V4.1-Flash-1017, and its Change Log says the calling method and pricing are unchanged. Send deepseek-flash. The other open question is settled too: deepseek-v4-pro was not remapped on September 14 and still bills at Pro rates.
What changed:
deepseek-flashnow serves V4.1-Flash-1017, with no price change. Who's affected: every DeepSeek API caller, including those still on legacy Flash names ordeepseek-v4-pro. What to do: pindeepseek-flash, keep Pro only if your evals need it, and plan for Search and Fetch billing from October 31.
What happened to DeepSeek V4.1 Flash on October 17?
DeepSeek's Change Log says V4.1 Flash "has been upgraded to DeepSeek-V4.1-Flash-1017" and that you "simply use deepseek-flash to access the latest model." The web and app models moved to the same version.
DeepSeek reports gains over the September 10 release on its own agentic and coding benchmarks. These are vendor numbers, not an independent test.
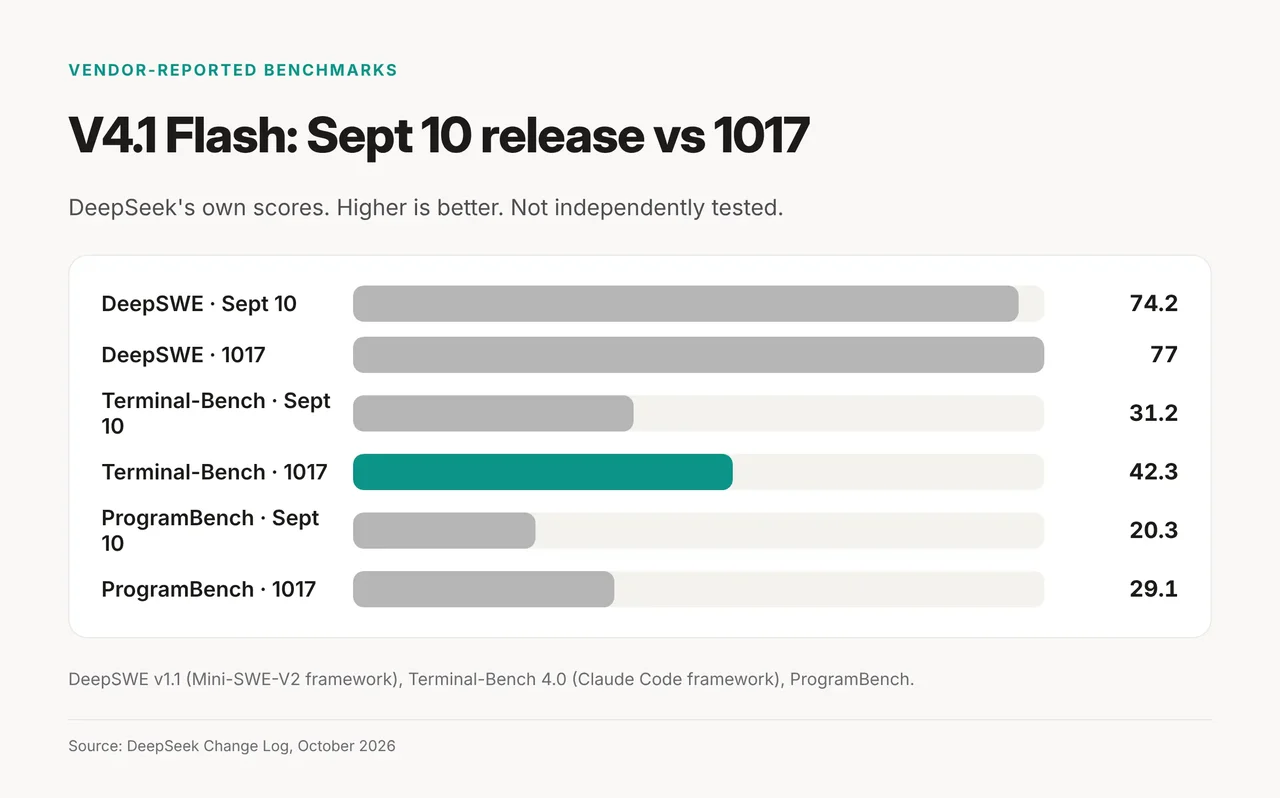
DeepSWE v1.1 went from 74.2 to 77.0, Terminal-Bench 4.0 from 31.2 to 42.3, and ProgramBench from 20.3 to 29.1. DeepSeek ran Terminal-Bench with the Claude Code framework and DeepSWE with Mini-SWE-V2.
Before and after: what does each model ID resolve to now?
The model behind deepseek-flash changed, while the prices and the Pro path did not. This table compares our September 13 post with DeepSeek's live Models & Pricing page on October 21.
| Model ID | September 13 | October 21 | Billed at |
|---|---|---|---|
deepseek-flash | V4.1-Flash | V4.1-Flash-1017 | Flash |
deepseek-v4-flash, deepseek-v4-flash-vision-exp | Legacy aliases to V4.1-Flash | Still accepted, served by 1017 | Flash |
deepseek-v4-pro | V4-Pro-0813, with a Sept 14 remap announced | V4-Pro-0813, no remap | Pro |
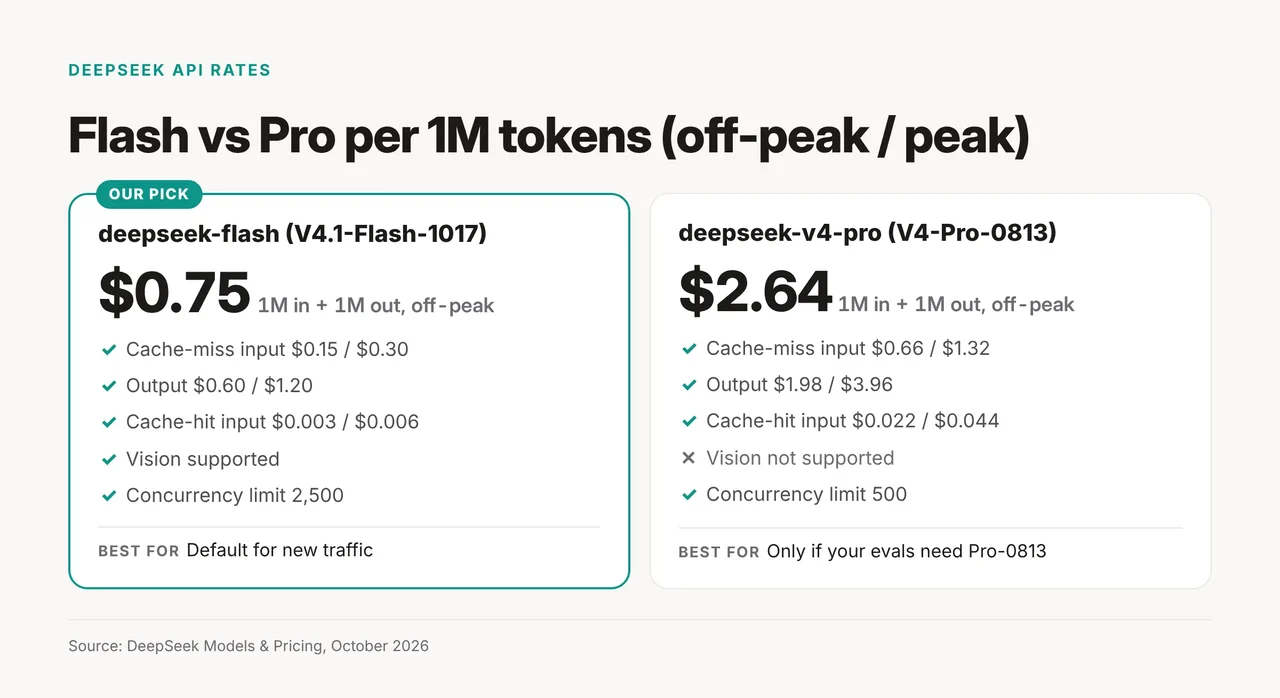
Both models list a 1M context and 384K maximum output. Flash supports vision and a concurrency limit of 2,500, and Pro has no vision and a limit of 500. DeepSeek describes Flash as a 552B-parameter MoE with 8B active parameters for input and 16B for output.
| Per 1M tokens (off-peak / peak) | Flash | Pro |
|---|---|---|
| Cache-hit input | $0.003 / $0.006 | $0.022 / $0.044 |
| Cache-miss input | $0.15 / $0.30 | $0.66 / $1.32 |
| Output | $0.60 / $1.20 | $1.98 / $3.96 |
Pro costs 4.4 times Flash on cache-miss input and 3.3 times on output. One million input plus one million output tokens costs $0.75 on Flash off-peak against $2.64 on Pro.
What does it mean for you?
New callers
Use deepseek-flash. It is the canonical ID, it gets 1017 automatically, and it carries the higher concurrency limit.
Legacy Flash alias users
Your calls already reach 1017 at Flash prices. DeepSeek says the old models behind those names "have been retired," so switch to deepseek-flash before the aliases go too.
Pro users
Pro keeps running. A Change Log entry dated September 10 says DeepSeek will "continue providing API services for DeepSeek V4 Pro after September 14, 2026, with the billing method remaining unchanged." Keep it only if your regression suite needs Pro-0813, because DeepSeek's September 10 news post says it is "phasing out V4-Pro."
What should you do now?
- Before October 31, 16:00 UTC: count your Search and Fetch calls through DeepSeek Harness, Claude Code or Codex. They are free today. DeepSeek's pricing page bills the standalone Search and Fetch APIs at $0.75 per 1,000 successful requests each. DeepSeek has not said whether the Harness, Claude Code and Codex tool calls will bill at that standalone rate after October 31, so treat it as an upper reference until it does.
- Now: replace
deepseek-v4-flashanddeepseek-v4-flash-vision-expwithdeepseek-flash. - Now: upgrade to DeepSeek Harness v0.2.1-rc.1 or later, which DeepSeek's 1017 release note recommends for the new model.
- This sprint: rerun your evals on 1017 and decide whether Pro still earns its 3.3 times output price.
- Ongoing: move batch jobs off-peak. Peak runs 01:00-04:00 and 06:00-10:00 UTC on weekdays, and off-peak rates are half of peak. Chinese public holidays now count as off-peak in full.
What is still unconfirmed?
DeepSeek's September 10 news post still says all deepseek-v4-pro requests "will route to V4.1-Flash" from September 14. The pricing table and Change Log contradict it, and they reflect current policy. We found no notice explaining the stale post and no V4.1-Pro release date.
Related coverage
See our DeepSeek V4.1 Flash model page and the DeepSeek tool profile. To set DeepSeek against other assistants, try ChatGPT vs DeepSeek vs Gemini. For routing across vendors, read how to pick the right AI model for every task and our GPT-6 Astra vs Claude Fable 5.1 vs Gemini 3.8 Flash comparison.